
Open source · Apache 2.0
Use the open specification
Read the rules and the formula on GitHub, run them against your own OTLP data, and propose changes. Discussion happens in the #instrumentation-score channel on the CNCF Slack.
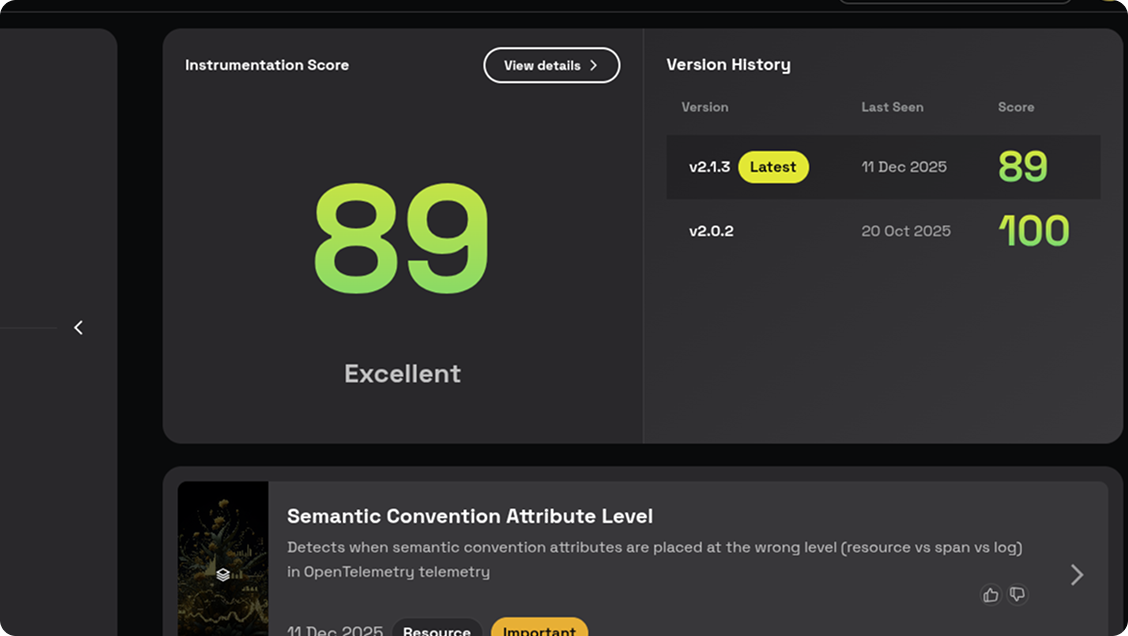
The Instrumentation Score is a 0–100 measure of how well a service's OpenTelemetry® telemetry follows best practices and semantic conventions. It checks the traces, metrics, logs, and resource attributes a service already sends against 25 open rules, and weighs each failed rule by its impact.

How it is calculated
The score is a meta-signal: a signal about the quality of your signals. Every rule passes or fails for a service, and failed rules cost points in proportion to their impact, so one Critical failure costs four times as much as one Low failure. Nothing is capped, and fixing the most severe problems first always moves the score the most.
An implementation reads the OTLP data a service already sends, grouped by service.name, over a sliding window that defaults to 30 days. The score follows the service as it changes: spans that helped during development can become noise once it is stable.
Each of the 25 rules is a pass or fail condition on resources, spans, metrics, logs, or the SDK. A rule with several conditions passes only when all of them hold.
The score is the weighted share of passed rules: the sum of passed rules times their weight, divided by the sum of all rules times their weight, times 100.
| Impact | Weight | Rules |
|---|---|---|
| Critical | 40 | 5 |
| Important | 30 | 13 |
| Normal | 20 | 6 |
| Low | 10 | 1 |
All rules passing: 720 weighted points
| Score | Category | Meaning |
|---|---|---|
| 90–100 | Excellent | A high standard of instrumentation quality. |
| 75–89 | Good | Solid quality; minor improvements are possible. |
| 50–74 | Needs Improvement | Tangible issues that need attention. |
| 0–49 | Poor | Significant problems that need urgent action. |

The rules
The rules come from OpenTelemetry semantic conventions and community practice. This table is generated from the specification repository, most severe first; each rule ID links to its full definition and criteria.
Synced from the specification on 2026-09-24 (commit 0ef3cc6).
Showing 25 of 25 rules
Log records do not contain sensitive data such as PII, financial identifiers, credentials, or health information.
Backends give more people access than production databases do, so personal data in logs becomes a compliance problem.
How-to →Metrics do not contain sensitive data such as PII, financial identifiers, credentials, or health information.
Personal data in metric names, labels, or exemplars reaches everyone with dashboard access.
How-to →service.name is present.
service.name is required by the semantic conventions; without it, telemetry belongs to nobody.
Resource attribute values do not contain sensitive data such as PII, financial identifiers, credentials, or health information.
Credentials in resource attributes, often from command-line arguments, are copied onto every record a process sends.
How-to →Spans do not contain sensitive data such as PII, financial identifiers, credentials, or health information.
Spans record query text, URLs, and headers, which is where personal data and tokens leak.
How-to →Debug-level logs are not enabled in production environments for longer than 14 days.
Debug logs left on in production cost storage, can carry sensitive values, and bury the records you need.
How-to →Log records have their severityNumber set.
Without a severity number every record looks the same, so you cannot filter or alert on errors.
Metric attributes have bound cardinality.
Unbounded attribute values multiply time series, which slows queries and raises storage cost.
How-to →Metrics have useful metric units.
A value without a unit cannot be read: 1% of memory, 1 MB, and 1 GB look the same.
How-to →Metric names are consistently associated with the same metric unit.
When one metric name carries different units, every query across services mixes them.
How-to →Metric names do not equal semantic convention attribute keys.
A metric named like a semantic convention attribute, such as http.response.status_code, confuses queries and readers.
service.instance.id is unique across logical resources within a given service.name.
An instance ID shared by several pods is worse than none: it merges their telemetry.
How-to →k8s.pod.uid is present in telemetry collected from applications running on a Kubernetes cluster, or from the control pane of the Kubernetes cluster itself.
k8s.pod.uid lets the Collector attach Kubernetes metadata reliably, even behind a service mesh.
Semantic conventions attributes are used at the right level.
Attributes at the wrong level, such as service.name on a span, break queries that look where the conventions say they live.
deployment.environment.name is present.
Without an environment, staging and production data mix in the same views and alerts.
Span names have bound cardinality.
Criteria still being defined in the specification.
Span names with IDs or literal URLs defeat grouping and can blow up backend indexes.
How-to →Root spans are not CLIENT spans.
A trace that starts with a CLIENT span is missing the work that caused the call, or lost its context.
Traces do not contain a high number of short duration spans.
Dozens of spans shorter than 5 ms in one trace add overhead and hide the operations that matter.
How-to →Histogram metrics consistently use the same histogram buckets per metric name.
Different buckets for the same histogram make aggregated quantiles less precise.
Metric names do not contain the name of the metric unit.
The unit belongs in the unit field; a name that repeats it breaks when the unit changes.
How-to →service.instance.id is present.
service.instance.id tells instances of a service apart without combining other attributes.
service.criticality uses a valid enum value.
Standard criticality values let tooling rank alerts and incidents consistently across teams.
Traces contain a limited number of INTERNAL spans per service.
Many INTERNAL spans in one trace usually mean over-instrumented code paths that add noise and cost.
Traces do not contain orphan spans.
A span whose parent never arrives means context propagation broke and the trace is incomplete.
How-to →Dependencies (language and runtime) are supported by the SDK.
Languages and runtimes outside the SDK's support window miss fixes and current semantic conventions.

Worked example
A checkout service sends traces, metrics, and logs and fails 4 of the 25 rules. Here is how those findings become its score. Fix them one by one to see what each is worth.
url.full on password-reset spans carries the reset token in its query string.
No deployment.environment.name, so staging and production share dashboards.
Custom queue metrics are exported without a unit.
No service.instance.id, so the three replicas cannot be told apart.
83.3: Good
Score 83.3, GoodWith every rule passing, the service would hold all 720 weighted points. The 4 failures cost 120, which leaves 83.3: Good.
Fixing the Critical token leak alone raises the score to 88.9. Adding the two Important fixes reaches 97.2, which is Excellent.
That ordering is the point of the weights: the score tells a team which fix to make first.

Get your score
The specification is open, so anyone can implement it. OllyGarden Insights is a hosted implementation that keeps the score current for every service.
Open source · Apache 2.0
Read the rules and the formula on GitHub, run them against your own OTLP data, and propose changes. Discussion happens in the #instrumentation-score channel on the CNCF Slack.
Free plan · No credit card
Send a sample of your OTLP data to OllyGarden Insights and get a score for every service, the findings behind it, and remediation guidance. The Free plan includes the Instrumentation Score, with no credit card.

In real fleets
These findings come from our anonymized case studies. Each one is a rule that failed in production or staging telemetry, and a real cost behind it.
Read the case studies →of about 500 services set a deployment environment; 56% set service.instance.id.
RES-007 (show the rule)RES-001 (show the rule)
Read the case study →services were flagged for personal data in logs in the first week.
Read the case study →of log records arrived with no severity, because the log bridge dropped the level.
Read the case study →to catch real user email addresses copied into a metric label by a new log-to-metric rule.
Read the case study →What teams ask us about the Instrumentation Score, the specification, and how to use it.
The Instrumentation Score is a 0–100 measure of how well a service's OpenTelemetry telemetry follows best practices and semantic conventions. It checks the traces, metrics, logs, and resource attributes a service already sends against 25 open rules, and weighs each failed rule by its impact.
Each rule has an impact level with a weight: Critical 40, Important 30, Normal 20, and Low 10. The score is the sum of the weights of the rules a service passes, divided by the sum of the weights of all rules, times 100. The current specification has 5 Critical, 13 Important, 6 Normal, and 1 Low rules.
The specification maps scores to four categories: 90 to 100 is Excellent, 75 to 89 is Good, 50 to 74 is Needs Improvement, and 0 to 49 is Poor. Do not chase 100; a score of 75 or more is a sound target for most services. Fix Critical failures first: one of them, such as personal data in spans, costs 40 of 720 points and leaves 94.4, and two leave 88.9, which is Good.
Yes. The specification is open source under the Apache 2.0 license, and its maintainers work at Splunk, New Relic, Dash0, and OllyGarden. Implementations may not add rules of their own, so the same telemetry gets the same score in any tool.
OllyGarden started the specification in 2025 and hosts it today under an open governance model. Maintainers from Splunk, New Relic, Dash0, and OllyGarden review changes, and the goal is to move it to a neutral foundation such as the CNCF or the OpenTelemetry project.
An SLO measures how a service behaves for its users, such as latency or error rate. The Instrumentation Score measures the telemetry itself: whether the data your SLOs, dashboards, and alerts are built on is complete, consistent, and safe. A service can meet its SLOs while its telemetry hides problems.
Generic data quality checks validate schemas, freshness, or volumes. The Instrumentation Score checks telemetry against OpenTelemetry semantic conventions and instrumentation practice, such as service identity, units, cardinality, broken traces, and sensitive data, and summarizes the result in one number you can compare across services and tools.
Not always. Many failed rules can be fixed in the OpenTelemetry Collector: the transform processor, written in the OpenTelemetry Transformation Language (OTTL), can add missing resource attributes, move attributes to the right level, or redact sensitive values, and the filter processor can drop debug logs and noisy spans. Fixing the instrumentation at the source is still the better long-term answer.
Yes. The first draft, published in June 2025, started every service at 80 and added or subtracted fixed points per rule. The community replaced it with the weighted share of passed rules described on this page, which keeps the score between 0 and 100 without clamping and makes every rule's effect proportional to its impact.
The rules cover resource attributes, spans, metrics, and logs, plus one rule on SDK support for the language and runtime. New rules are added through the specification repository.
Implement the open specification against your own OTLP data, or use OllyGarden Insights, which computes the score continuously for every service and shows the findings behind it. The Insights Free plan includes the Instrumentation Score, with no credit card.
Yes. Open an issue or pull request in the instrumentation-score/spec repository on GitHub, or start a discussion in the #instrumentation-score channel on the CNCF Slack. Every rule needs a rationale, pass or fail criteria, a target, and an impact level.
Learn more
Send a sample of your OpenTelemetry data to Insights and see the score for every service, with the findings behind it.
